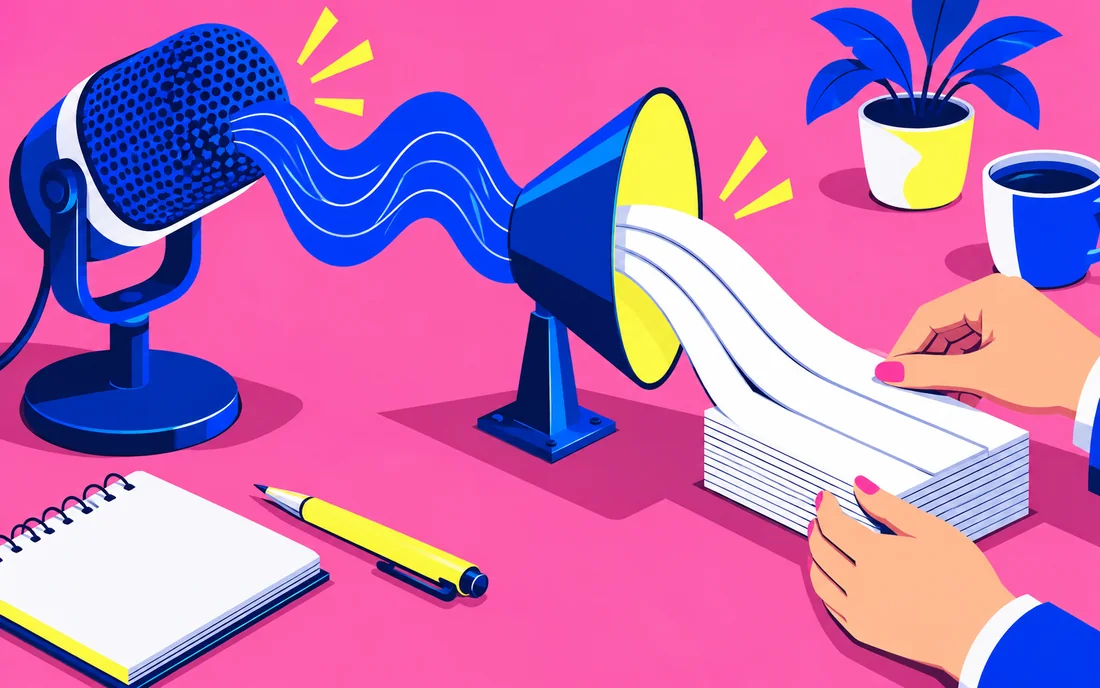
Speech recognition converts spoken audio into text or another usable representation. Accuracy depends on audio conditions, language, terminology and the system. Recognition and summarisation are separate stages, so each can introduce different errors into a meeting or transcription workflow.
What affects the result
Recognition quality depends on the recording, speakers, language and vocabulary. Background noise, overlapping speech and unfamiliar names can create errors. Punctuation and speaker labels may add interpretation rather than reproduce an explicit feature of the audio.
Review the details that matter
In a meeting, verify names, quantities, dates and commitments. A single missing ‘not’ can reverse a sentence. Preserve timestamps when available so a reviewer can return to the relevant moment. If the audio is unclear, mark uncertainty rather than silently replacing it with a plausible phrase.
Build a sensible workflow
Capture audio with participant awareness and suitable settings for the situation. Provide a terminology list when the tool supports it, then correct recurring specialist terms. Test with realistic recordings rather than only clean demonstrations. For an illustrative interview workflow, create a transcript for navigation but listen to the original before publishing a quotation. Speech recognition can save substantial review time while leaving the source recording as the final reference for what was actually said.
A worked example
Use an authorised recording containing a person's name, a correction and a sentence with a negation. Compare a short segment with a human-checked transcript. Mark errors that change meaning, not only punctuation. If a later summary reports the wrong deadline, inspect whether the mistake began in recognition or in interpreting an otherwise correct transcript.
Questions readers ask
Are speaker attribution and word recognition the same thing?
No. A system can recognise the words but assign them to the wrong person. Evaluate both when the identity of the speaker matters.
Follow the evidence.
AI-assisted explanation with linked technical references. Examples are illustrative learning exercises, not reported customer deployments or experimental results.
Public sources support the factual background. Analysis and illustrative exercises are identified in the text. How we assess AI · Editorial standards
Spot a factual error or an outdated detail?