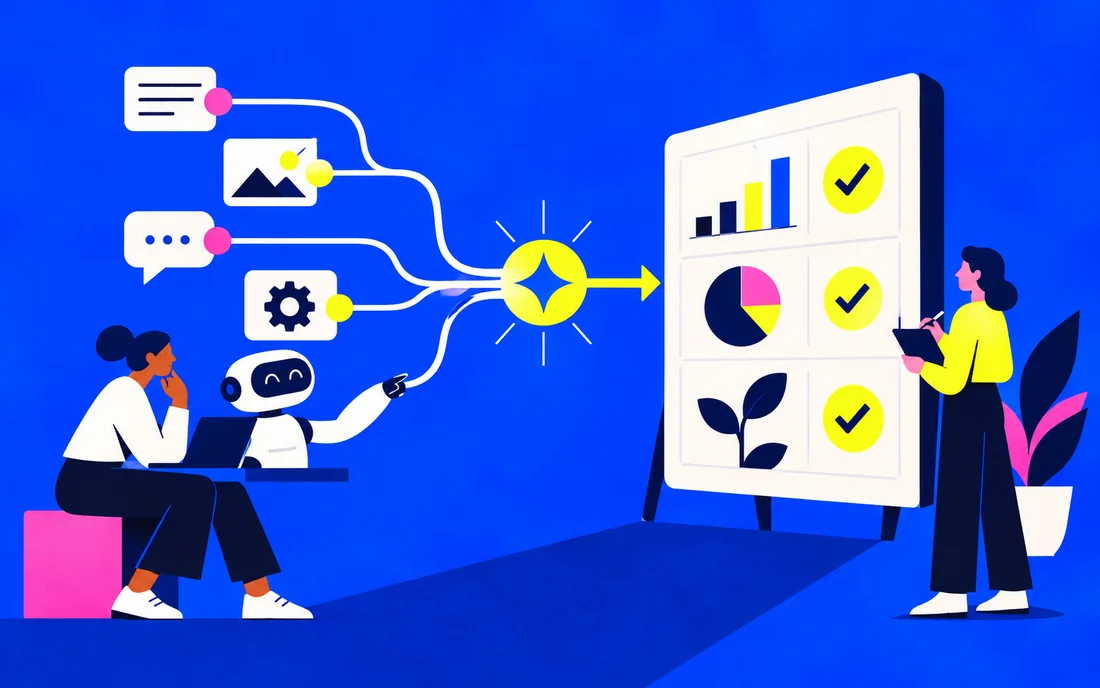
OpenAI’s September 16 post describes analytics across ChatGPT Work and Codex, including usage, costs, task categories and engineering outcome indicators. It explains how administrators can inspect adoption and how business owners can relate those observations to the work their teams perform.
Read the dated primary source ↓Activity is not an outcome
More messages, tokens or AI-assisted code do not by themselves prove better results. A team may be experimenting, correcting mistakes or handling more difficult work. Meaningful evaluation needs a starting point and measures such as accepted output, delivery time, defects or rework.
A useful measurement plan
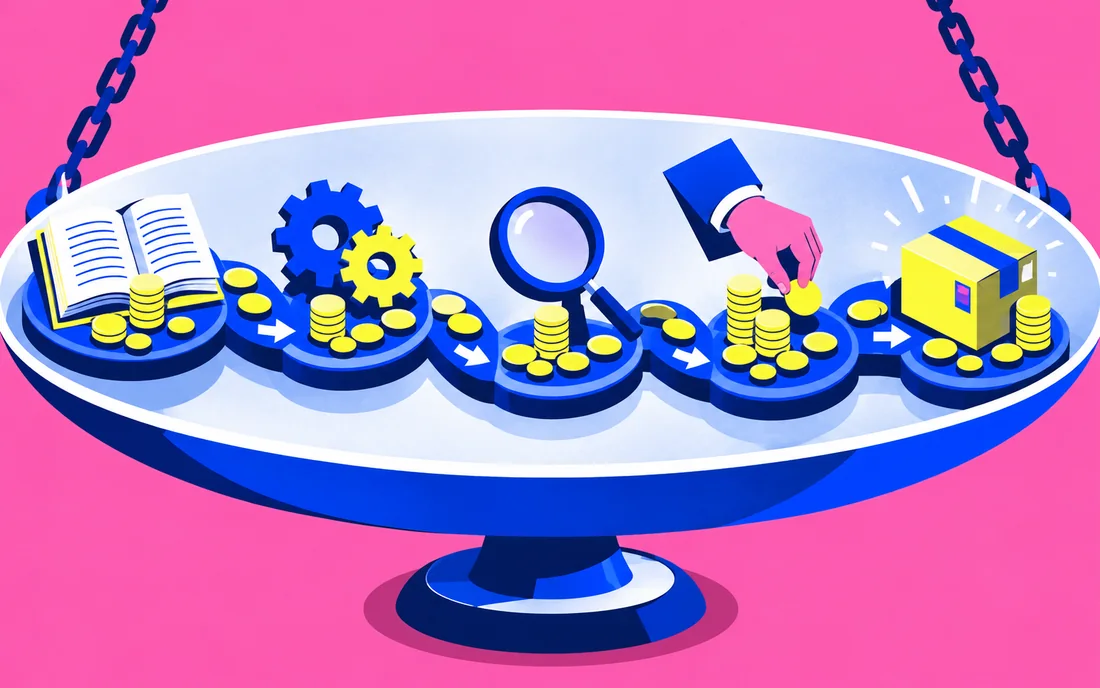
Choose one recurring task and compare complete effort before and after the change. Include setup, review and ongoing support. Treat hypothetical return calculations as illustrations, and keep actual measured outcomes separate from estimates of what saved capacity might be worth.
What this means in practice
Reporting AI usage becomes more useful when it connects activity with completed work and correction effort. A team can generate many drafts without saving time if each requires extensive review. Start from a defined process and baseline, then measure quality and useful completion alongside adoption.
Questions readers ask
Is a higher AI usage count proof of business value?
No. Track the outcome of the task, review effort and relevant cost against a baseline. Activity is one input to that assessment.
Follow the evidence.
Source-based coverage of the dated announcement below, with Promptwire analysis. Company-reported claims are attributed to their source. The update date reflects added context and answers; it does not change the original event date.
Public sources support the factual background. Analysis and illustrative exercises are identified in the text. How we assess AI · Editorial standards
Spot a factual error or an outdated detail?